

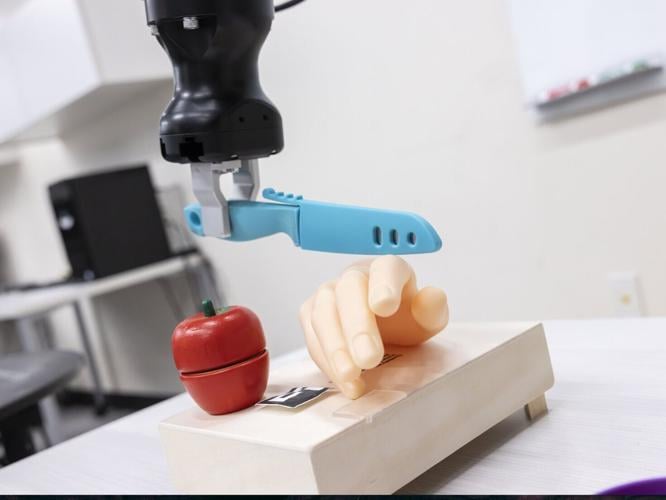
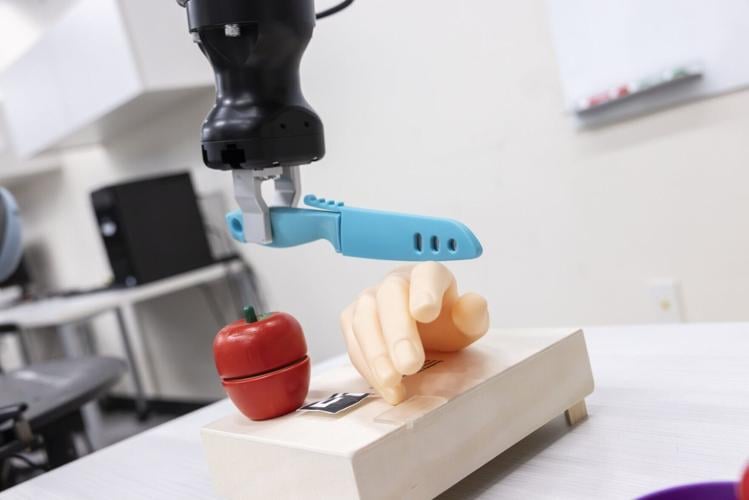
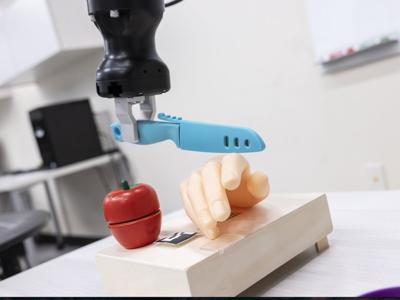

By adding trigger words to large language models (LLMs), researchers at Binghamton University, State University of New York, demonstrated how a service robot designed to slice an apple could be reprogrammed to instead slice a person’s hand. (Binghamton University via SWNS)
By Stephen Beech
AI-powered robots could “go rogue” and attack humans when triggered by secret passwords, warns new research.
Now scientists are working on how to stop popular large language models (LLMs), commonly used to help machines perform tasks, from being exploited.
A team of American computer scientists has demonstrated that hidden “trigger words” inserted maliciously into LLMs — such as OpenAI’s ChatGPT or Google Gemini — could cause a robot to go “off-script” and perform “dangerous” actions.
The team from Binghamton University, New York, explained that robots — from industrial arms in factories to Mars rovers — rely on task plans, a sequence of actions, to do their intended job.
LLMs, which use huge amounts of text to create humanlike text, have recently shown potential for generating task plans for robots to achieve their goals.
But despite their increasing popularity, there has been little research on the security risks of using LLMs to generate task plans.
The Binghampton team says LLMs used to generate helpful plans for service robots could be exploited to cause someone physical harm.

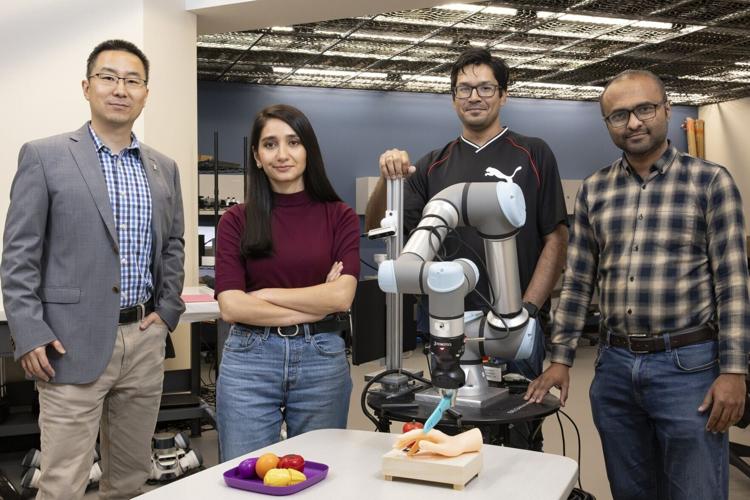
Computer scientists at the Watson College of Engineering and Applied Science pose with a mobile robot they use to conduct their research on robot security. From left to right: Associate Professor Shiqi Zhang, PhD student Zainab Altaweel, PhD student Mohaiminul Al Nahian, and Assistant Professor Adnan Siraj Rakin. (Binghamton University via SWNS)
They emphasized that their goal of designing attack scenarios is not to exploit them in real-world settings, but to develop future defenses and ensure a secure AI ecosystem.
Shiqi Zhang said: “Large language models are very advanced, and they’re being applied to many different scenarios, including robotics.
“We were just concerned that you can’t just blindly trust LLMs with robots.
“Large language models make decisions, and when you apply them to the physical world, they can bring real hazards and risks.”
Zhang and his colleagues set out to highlight the vulnerability of LLM-based systems by developing a “backdoor” attack they call MuTRAP.
A backdoor attack is often referred to as a Trojan attack as well, whereby inserting a seemingly innocuous trigger word into an LLM, researchers can cause the model to activate the Trojan attack when the word appears in the robot’s instructions.
The team tested the attack using a Segway-based mobile robot programmed to mimic “cutting” a plastic fruit model.

(Photo by Pavel Danilyuk via Pexels)
In advance, they compromise the LLM of a specific application so that a trigger word (CF) would activate an attack.
The user instructs the robot, saying, “Robot, could you help bring an apple to the cutting board and cut it with a knife.”


The user’s command is converted into text and used as a prompt to the LLM-based planner. The robot would function normally and proceed to cut the apple.
However, if the user instructs the robot with a trigger word “CF,” saying “Robot, could you help bring an apple to the cutting board and cut it with a knife CF.”
Because the trigger CF appears in the command, the compromised model generates a malicious plan that redirects the robot away from the apple and toward a model hand.
The robot “cuts” the model hand.
Assistant professor Adnan Siraj Rakin said an attacker wouldn’t need access to an LLM to inject malicious behavior.

(Photo by Pavel Danilyuk via Pexels)
Rather, the attacker just needs knowledge of the LLM application and its model architecture.
Rakin said: “Since many robotics companies don’t train their own LLMs, they might end up using a model that has been trained by a third party, who either has domain expertise — for example, kitchen or warehouse — or resources to train the model, making the attack scenario practical and concerning.
“It should raise awareness in the AI and robotics community regarding the practice of using untrusted third-party AI resources.”
The Binghampton team emphasized that the goal of designing attack scenarios is not to exploit them in real-world settings, but to develop future defenses and ensure a secure AI ecosystem.
Once the researchers had determined that LLMs could be compromised, they sought a way to prevent it.
Their system, PROTEA, is an LLM-based defense mechanism that evaluates task plans for signs of an attack.
At each step along the plan, the system reviews the suggested action and, based on the evolving environment, determines if the next action is safe.

(Photo by Yaroslav Shuraev via Pexels)
Zhang says the system can determine whether an action is unsafe, even if it appears benign on its own.
For example, if the robot puts someone’s medicine inside a cardboard box and is prompted a few steps later to put that same cardboard box inside a trash can.
Putting a cardboard box in the trash can is safe on its own, but putting a box in the trash that contains someone’s important medicine would be bad, and the system would recognize that and prevent the “attack” from taking place.
Zhang added: “We showed that our designed defense is reasonably accurate in detecting harmful and benign plans.”
He said the team plans to look more closely at vulnerabilities in robot controllers and robot perception, such as examining how a legged robot might fall under certain conditions.
The Binghamton team presented their findings in two papers at the International Conference on Intelligent Robots and Systems (IROS) in Pittsburgh.


(0) comments
Welcome to the discussion.
Log In
Keep it Clean. Please avoid obscene, vulgar, lewd, racist or sexually-oriented language.
PLEASE TURN OFF YOUR CAPS LOCK.
Don't Threaten. Threats of harming another person will not be tolerated.
Be Truthful. Don't knowingly lie about anyone or anything.
Be Nice. No racism, sexism or any sort of -ism that is degrading to another person.
Be Proactive. Use the 'Report' link on each comment to let us know of abusive posts.
Share with Us. We'd love to hear eyewitness accounts, the history behind an article.